Scrape.ly
A cloud web scraping platform with a store of 616 ready-made scrapers (Actors) that return JSON or CSV via API or MCP.
Link is nofollow until the page is claimed
A cloud web scraping platform with a store of 616 ready-made scrapers (Actors) that return JSON or CSV via API or MCP.
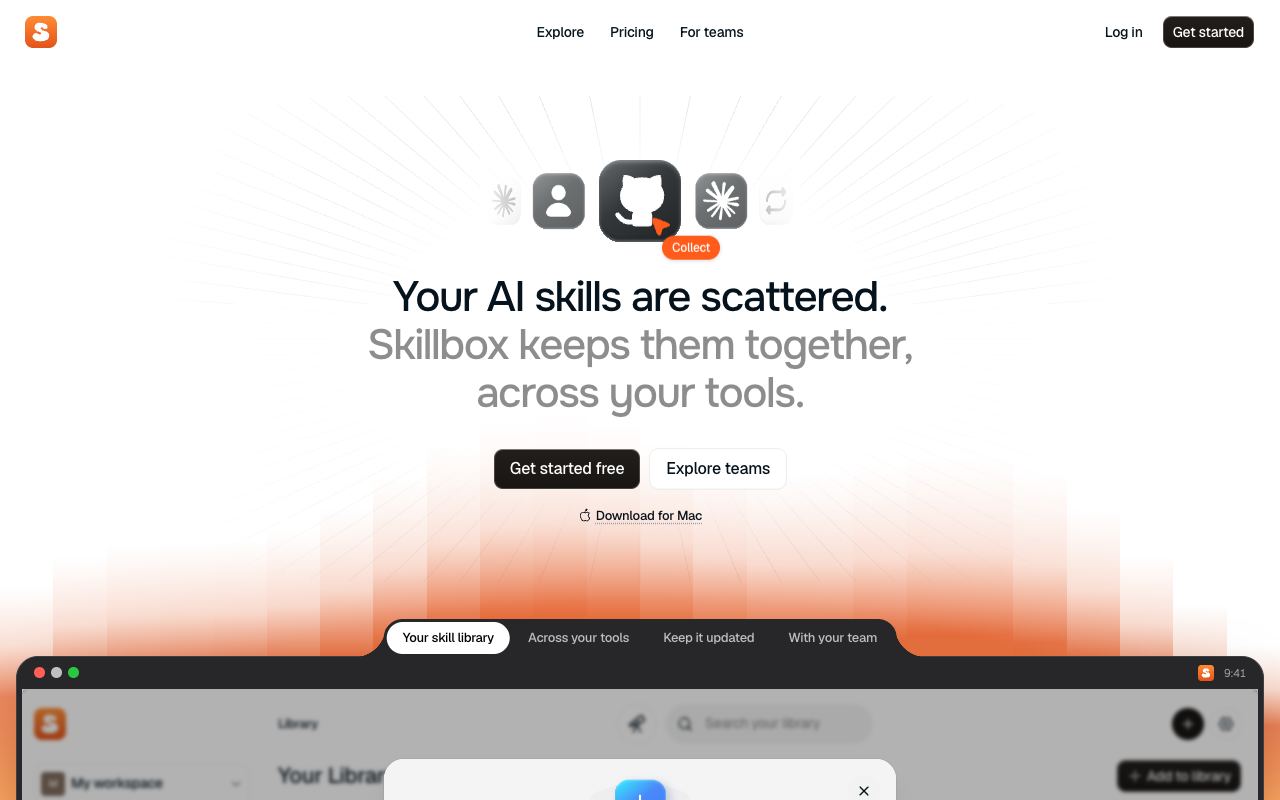
Right now it shows a scraped screenshot and a few lines. Claimed pages get a permanent dofollow link, a screenshot gallery, features, pricing, FAQ, your founder story, and the questions visitors ask.
Not yours, or want it gone? Remove this page.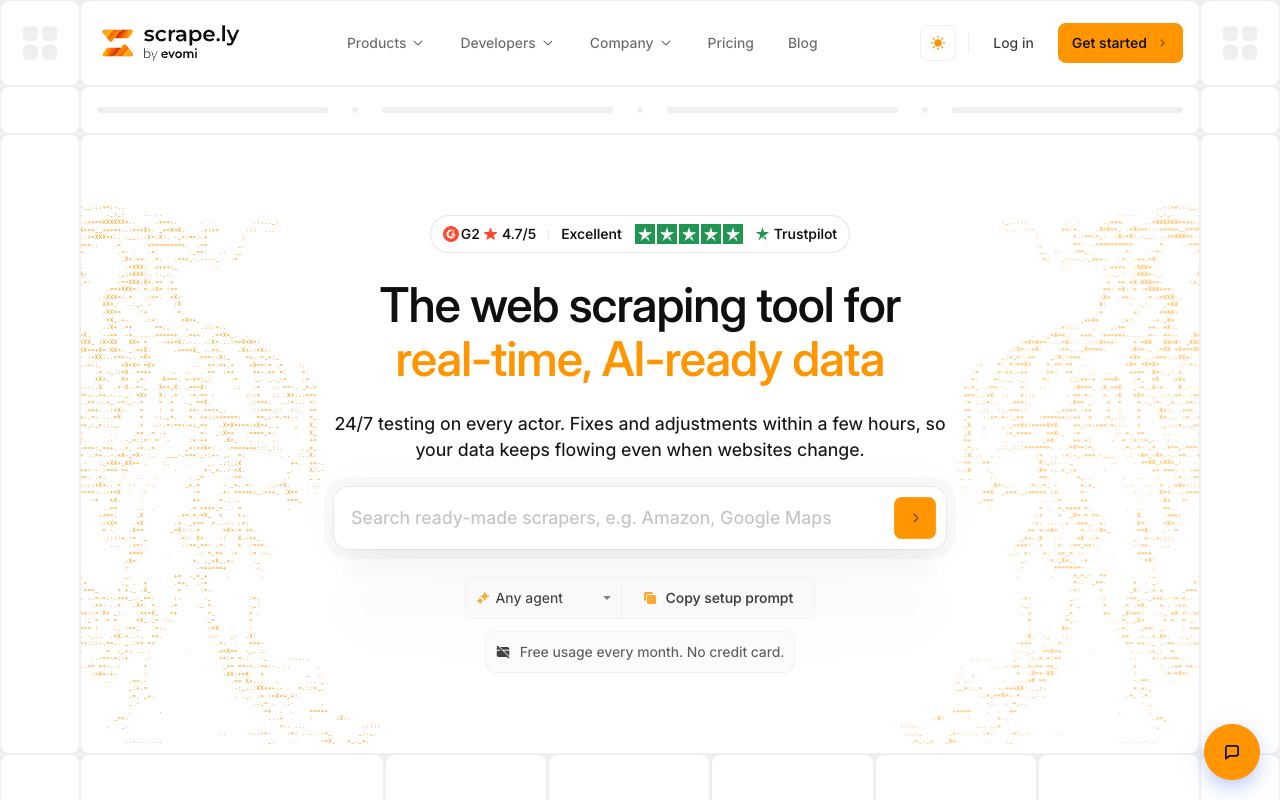
Homepage screenshot taken by Automateo. Claimed pages show the founder's own screenshots. Claim and replace it
Users run ready-made Actors (e.g. Google Maps, Instagram, TikTok scrapers) in the cloud, or build and deploy their own in JavaScript/TypeScript/Python with SDKs and a CLI. The platform handles proxies, a hosted browser, storage, scheduling and webhooks, and exports data as JSON, CSV, Excel, XML or RSS. Developers can publish Actors to the Store and earn 80% of what users pay. Collecting web data without managing scraping infrastructure, proxies, servers, or broken scrapers when sites change. Built for: Developers, data teams, and AI builders who need public web data; also non-developers like market researchers and enterprises needing custom pipelines. Main features: Store of 616 ready-made Actors; Cloud runtime to build and deploy custom Actors; MCP server for AI agents (Claude, Cursor, VS Code, ChatGPT); Managed proxies: 100M+ residential IPs, 195+ countries; Scheduling, webhooks, GitHub-triggered rebuilds; Export to JSON, CSV, Excel, XML, RSS.
Everything below fills in from the founder's answers or their ListingBro Listing Kit. Nothing to write twice.